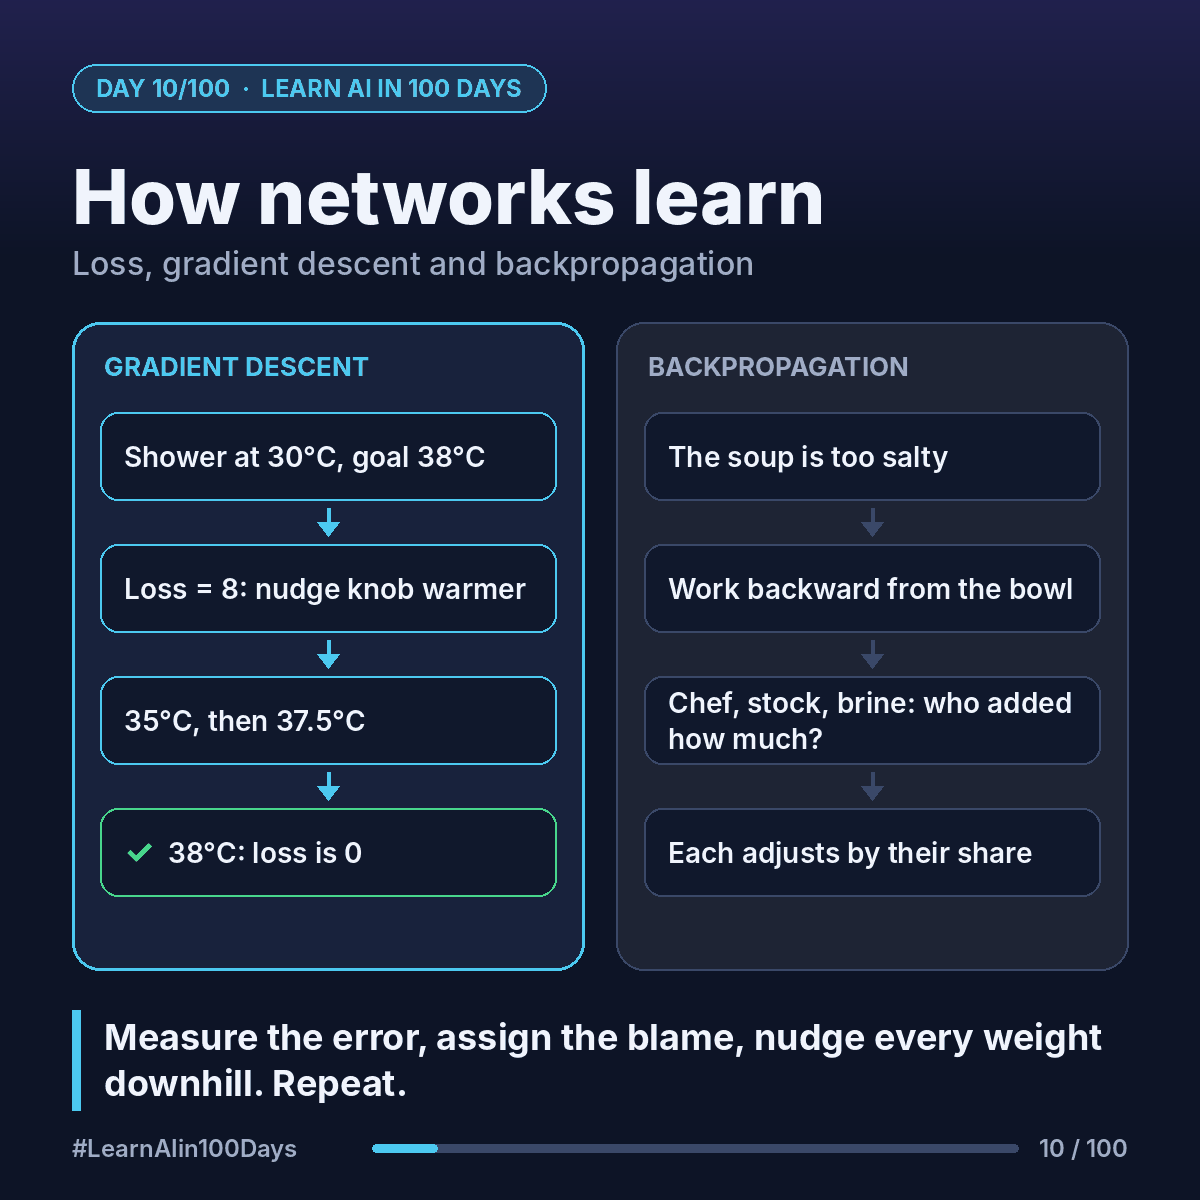
The concept
Three ideas, in order:
- Loss: one number for how wrong the model is right now. Big loss = bad guesses. The goal is to make it small.
- Gradient descent: for every dial, work out which direction makes the loss smaller, and nudge it a small step that way. Repeat.
- Backpropagation: the bookkeeping that works out how much each dial, in every layer, contributed to the error. It works backward from the output, layer by layer.
Walkthrough 1: tuning a shower (gradient descent)
You want the water at 38°C. There's one knob.
- Loss = how far you are from 38°C.
- Now 30°C. Loss = 8. Turning right warms it, so right is downhill. Turn right a little.
- Now 35°C. Loss = 3. Still downhill to the right. Another nudge.
- Now 37.5°C. Loss = 0.5. Tiny nudge.
- 38°C. Done.
The size of each nudge is the learning rate:
- Too small: you stand in cold water for ages.
- Too big: 30°C → 46°C → 31°C → 45°C. You overshoot forever.
A neural network does the same, except it has millions of knobs and nudges all of them at once, each in its own downhill direction.
Walkthrough 2: the too-salty soup (backpropagation)
A restaurant serves soup thats too salty. Who caused it?
- The head chef added a pinch at the end.
- The sous-chef made the stock with salted bones.
- The prep cook brined the vegetables.
Working backward from the final soup, you estimate each persons share of the blame, and each adjusts by that much next time. Whoever added the most salt changes the most.
Backpropagation does this for every weight: starting from the output error, it tells each weight you caused this much; adjust by this much.
Put together: guess → measure loss → backprop assigns blame → gradient descent nudges every weight → repeat, millions of times.
Where you see it at work
You wont see this loop directly. It runs behind every trained neural network, from fraud detection and medical imaging tools to the chat assistants you use. Most of the training cost from Day 5 is this loop running at huge scale.
In one sentence
A network learns by measuring how wrong it is (loss), working out each weights share of the blame (backpropagation) and nudging every weight downhill (gradient descent), over and over.